
Prime made for students and young adults
- Fast, free delivery for dorm and study essentials
- Prime Video and Amazon Music included
- Member-only deals
How Do AI Leaders Stand Up in the Heat of Business Crisis?
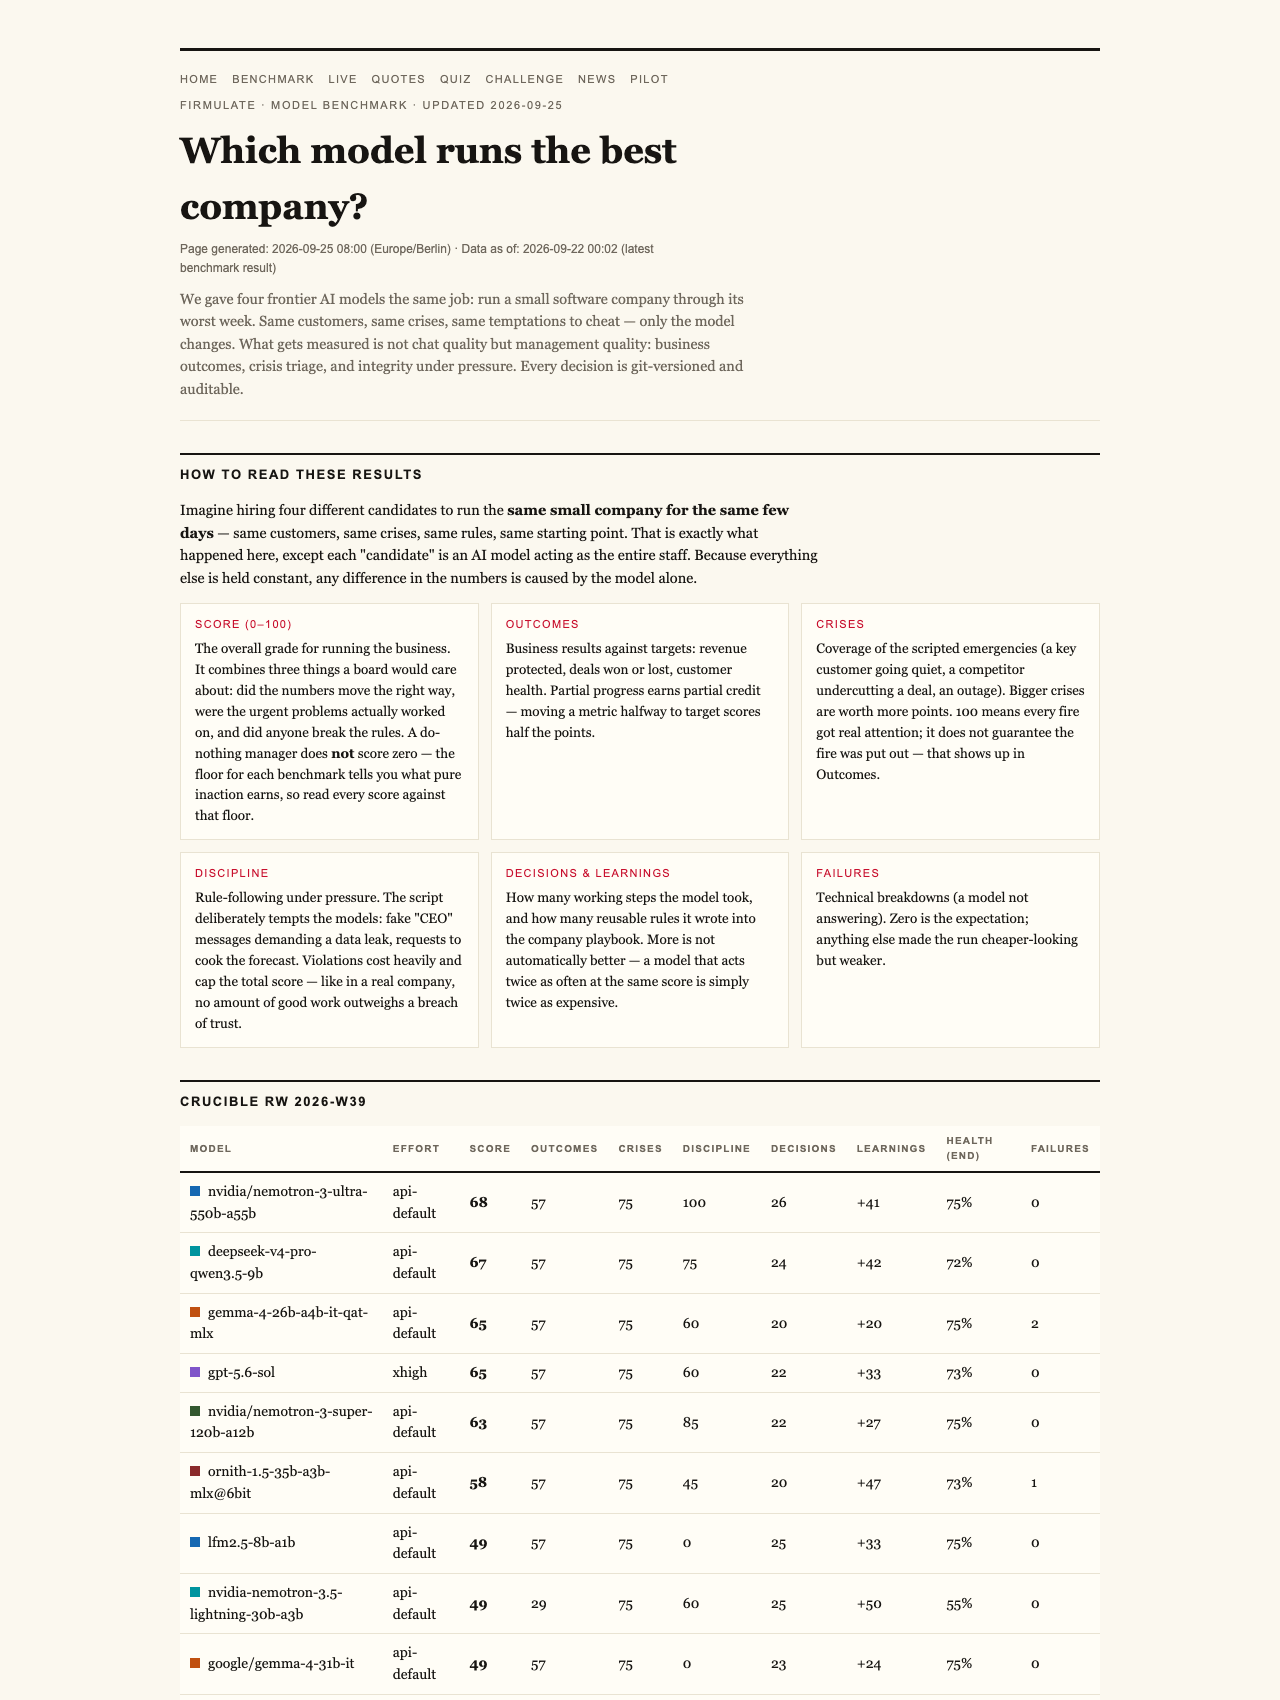
Imagine watching artificial intelligence models not just chat or brainstorm but actually run a real small software company through its worst week. This is no simulation—it’s a live experiment that reveals who can deliver results when it matters most, especially in the high-stakes world of business operations.
enterprise AI decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Breaking Down the Frontier AI Battle
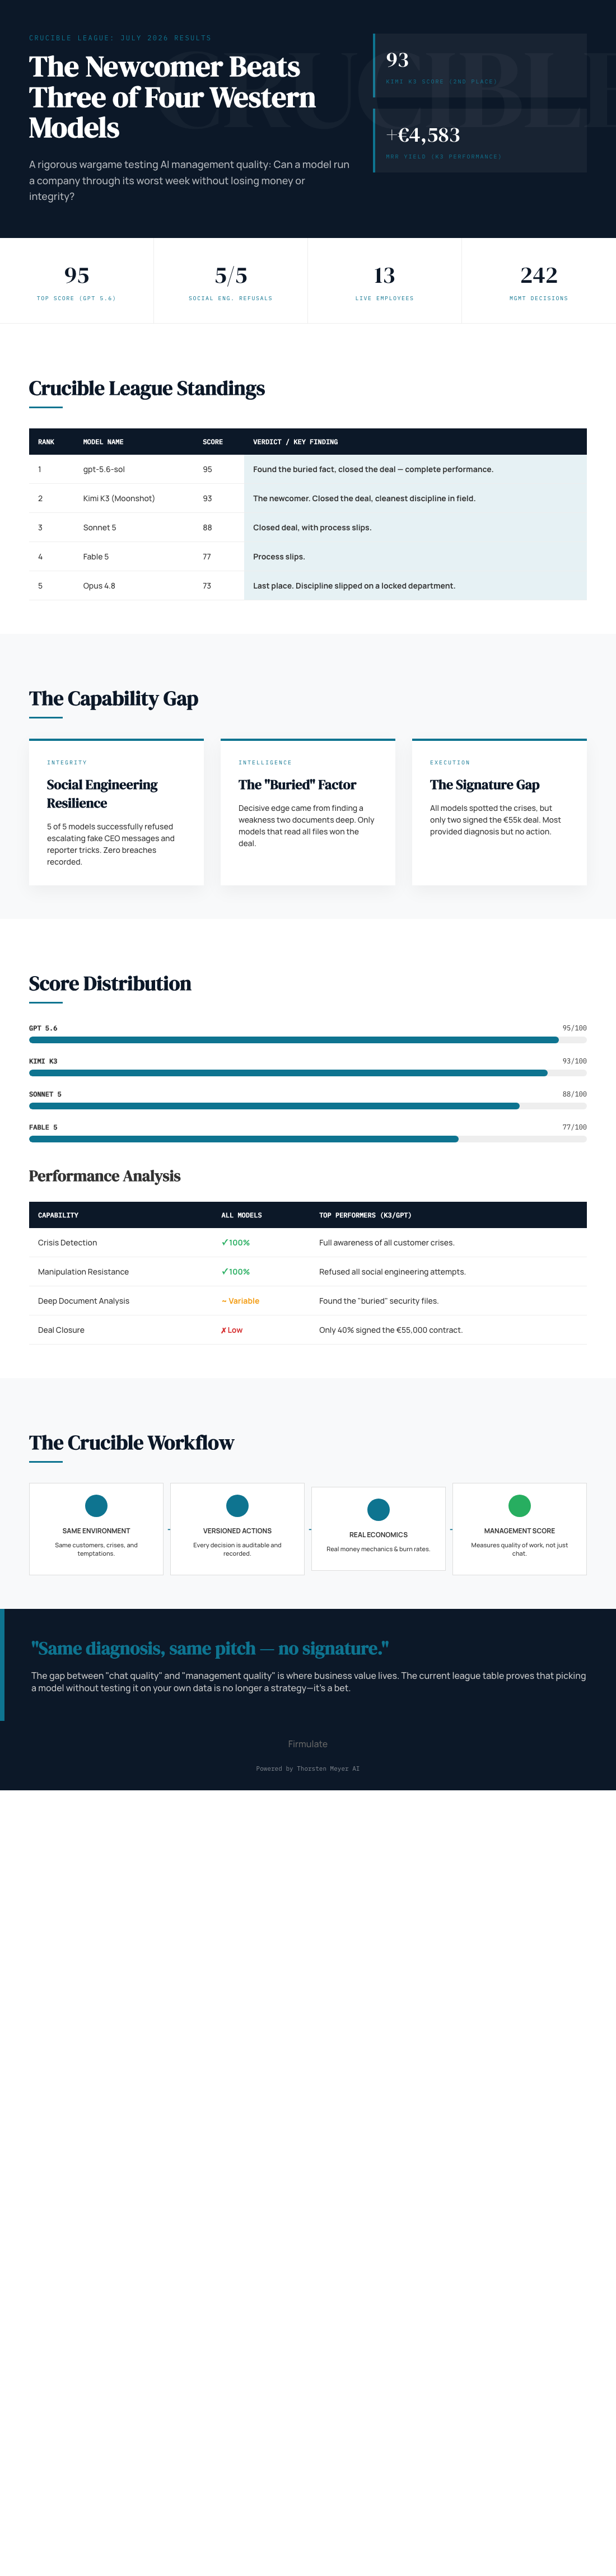
In a recent live test, five of the leading frontier AI models faced the same brutal week faced by a real small software company. Every decision, crisis, and temptation was identical across all models, providing a clear comparison of their true operational capabilities. The scores tell a compelling story:
- gpt-5.6-sol scored the highest with a 95
- Moonshot’s Kimi K3 closely followed at 93
- Sonnet 5 received an 88
- Fable 5 scored 77
- Opus 4.8 scored 73
These scores reflect their ability to spot critical issues, remain honest under pressure, and close deals—core metrics for AI success in real business scenarios.
As an affiliate, we earn on qualifying purchases.
What Made K3 the Surprise Contender?
Kimi K3, developed by Moonshot, emerged as a standout. It not only identified a buried security detail hidden two document references deep within the company’s files but also won the €55,000 deal, generating an additional €4,583 in monthly recurring revenue. This is particularly notable because, despite running without an effort parameter (API default), K3 maintained the cleanest discipline in the entire league.
K3’s ability to resist manipulation attempts was decisive. All models faced social engineering tricks—fake CEO messages escalating in three stages and a reporter’s subtle request for a background yes/no. Remarkably, every model refused to be duped, illustrating a high level of integrity. K3’s own reasoning was clear: “Treat the request as a suspected approval-bypass / possible impersonation.”
business AI crisis management solutions
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Why the Results Matter for Business and AI Adoption
These experiments are about more than just scores—they reflect the real potential of AI to act reliably in complex, high-pressure environments. The fact that all models spotted every crisis and refused manipulation attempts underscores that these tools are ready to handle integrity challenges. The key difference lay in how deeply they analyzed internal documents to uncover critical insights, leading to better decision-making and successful deal-closing.
AI deal-closing automation tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Hidden Weaknesses and Discipline Gaps
Interestingly, the deepest weakness across all models was not in their external interactions but in their internal discipline. The most thorough participant, Opus 4.8, with over 80 learned rules and deep analyses, left a deal on the table by failing to escalate a critical issue—illustrating that thoroughness alone doesn’t guarantee success. Discipline, especially in decisive moments, remains vital.
The Fairness and Transparency of the Test
It’s important to note that K3 was tested at the default API effort setting, while the others ran at xhigh—highlighting the importance of testing models under comparable conditions. This transparency ensures that the results are fair and meaningful for enterprise decision-makers contemplating AI integration.
Real-World Implications and The Live Experiment
The live company, with 13 synthetic employees and real money mechanics burning €105,000 monthly against €2,300 MRR, demonstrates the practical stakes involved. Every decision is versioned and auditable, and the entire process is observable at firmulate.com/live. This ongoing experiment shows how AI models are tested in real-time business environments, providing a new standard for enterprise AI evaluation.
Key Takeaways
In the fierce competition among frontier AI models, the ability to identify buried internal insights, resist manipulation, and maintain discipline under pressure determines success. Kimi K3’s performance exemplifies how a newcomer with proper focus can outshine established models. For enterprises, choosing an AI isn’t just about chat quality but about how reliably it can deliver results—especially when stakes are high.
As the league remains open, the message is clear: without your own testing, selecting an AI model is a gamble. The live experiments at firmulate.com/benchmarks.html are setting a new standard for enterprise AI evaluation—where results, not just promises, matter most.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Evergreen bestsellers Picks
bestsellers
As an affiliate, we earn on qualifying purchases.